Oído: Open-Vocabulary Speech Recognition on a $5 ESP32-S3
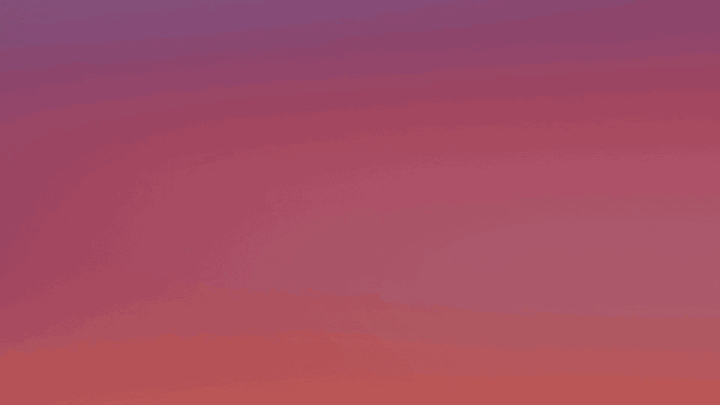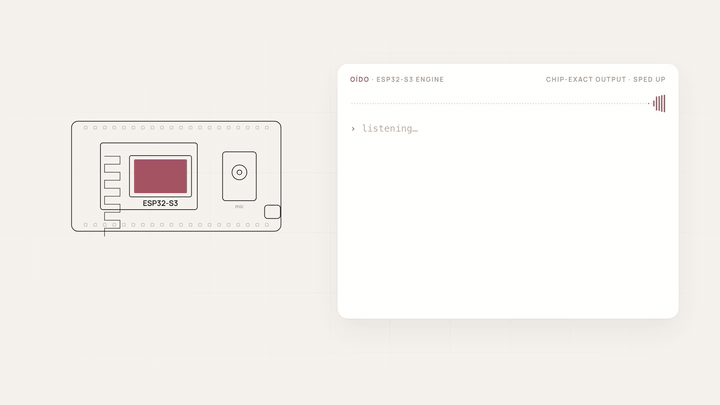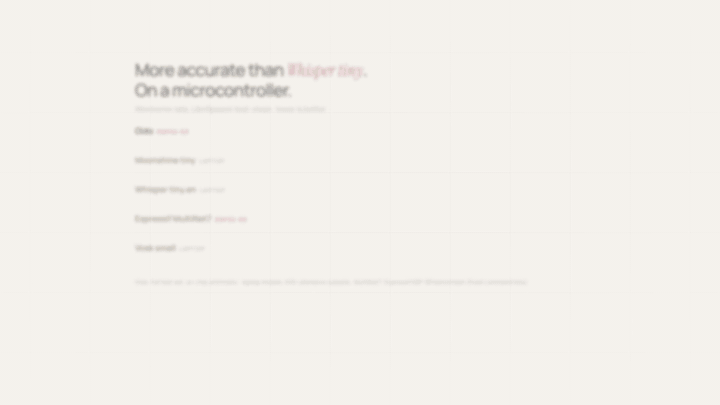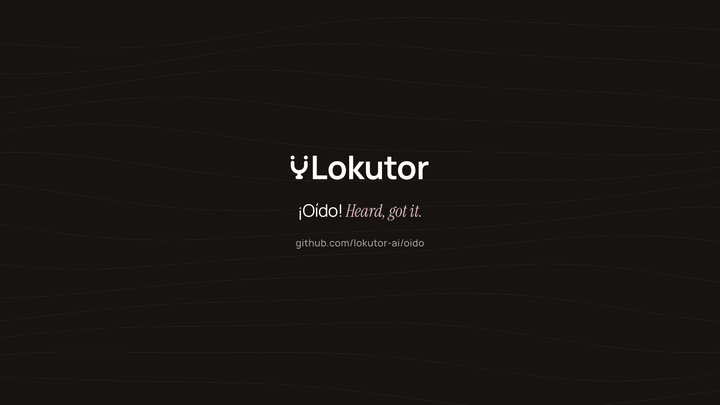
Oído running on an ESP32-S3: the animated demo shows real transcripts produced on chip, sped up for brevity.
- ESP32-S3-WROOM-1-N16R8 (DevKitC-1 class)
What You Will Build and Why It Matters
Oído turns a stock ESP32-S3 into a stand-alone speech-to-text engine that can transcribe any English or Spanish sentence — no cloud account, no fixed command list, no dedicated neural accelerator. It achieves 3.7% word error rate on LibriSpeech test-clean using a quantized NVIDIA Conformer-CTC Small model running directly on the chip's dual Xtensa LX7 cores at 240 MHz.
For makers, this removes the two biggest blockers in voice-controlled projects: network dependency and ongoing API costs. Once flashed, the board transcribes speech entirely on-device. The accuracy numbers put it ahead of several laptop-class systems on the same benchmark — Whisper tiny.en scores 6.3% and Vosk small 9.9%, both running on full computers with floating-point math. In noise-robustness testing across 14 conditions, Oído's mean word error rate (8.4%, or 7.5% with the language model) also beats those baselines.
Four model variants let you balance accuracy, flash footprint, latency, and language: int8 (14.0 MB), int4 (8.3 MB), a streaming-trained English model for lower-latency voice-agent pipelines, and a Spanish model trained on over 2,400 hours of speech.
What You Need
Hardware
- ESP32-S3-WROOM-1-N16R8 (DevKitC-1 class) — the board documented in the project. It must have 8 MB PSRAM and 16 MB flash; boards without PSRAM will not work. The CPU runs at 240 MHz.
Software
- ESP-IDF 5.5.1 — the version all published measurements were taken on.
- Python — for the live demo script and the evaluation pipeline.
- Model files — downloaded from Hugging Face. Choose based on your use case:
| Goal | Model file(s) | Flash used |
|---|---|---|
| Best English accuracy | nemo8.tnm + nemo_lm.tlm |
14.0 + 1.3 MB |
| Smallest flash footprint | nemo4.tnm |
8.3 MB |
| Streaming / voice agents | oido_stream.tnm (+ optional LM) |
14.0 + 1.3 MB |
| Spanish | oido_es.tnm + oido_es.tlm |
14.0 + 1.3 MB |
The language model files (nemo_lm.tlm, oido_es.tlm) are optional. Each adds 1.3 MB and reduces word error rate by 0.4–0.8 points on clean speech by enabling CTC prefix beam search instead of greedy decoding.
Typical use cases
Add open-vocabulary voice control to any ESP32-S3 project without a cloud subscription or a fixed command list. The chip handles all inference locally.
The streaming model processes audio in 1.28-second chunks as it arrives, cutting the wait for final text roughly in half compared with utterance mode — useful for voice-to-text pipelines feeding a local LLM.
A dedicated Spanish model trained on over 2,400 hours of speech supports both streaming and full-context modes in the same file, running at the same speed as the English model.
The host build, evaluation scripts, and published JSON results make Oído a reproducible baseline for comparing quantized ASR models on microcontrollers.
How It Works
The inference engine is written in C and runs under ESP-IDF. The acoustic model is NVIDIA's Conformer-CTC Small, quantized to 8-bit integers (or 4-bit for the int4 variant) and stored in Oído's .tnm format. The firmware extracts log-mel features from microphone audio or from clips stored in flash, runs them through the Conformer encoder, then decodes using greedy CTC or — when the language model is present — CTC prefix beam search with a beam width of 4.
The optional language model is a 1.3-million-parameter GRU trained on public-domain books from the LibriSpeech LM corpus.
Memory layout: the int8 model occupies 14.0 MB of flash. At runtime, working memory peaks at 2.4 MB of PSRAM for a 20-second utterance; remaining PSRAM caches the most-reused weight tensors. At least 122 KB of internal RAM stays free in utterance mode (72 KB in streaming mode). On a 20-second clip the chip computes at 461 million cycles per second of audio, running at 2.0 cycles per executed instruction.
Streaming mode: oido_stream.tnm processes audio in 1.28-second chunks (32 frames) with 5 seconds of left context as speech arrives. Partial transcripts appear while you speak. On one core at 240 MHz the real-time factor in streaming mode is 1.96×, so final text for a 4-second command arrives roughly 4 seconds after you stop — about half the wait of utterance mode.
The board's transcripts are bit-identical to those of the instruction-accurate QEMU emulator on all 27 measured clips, confirming that the firmware can be validated on a PC before touching real hardware.
Flashing and Running Oído
1. Set up the toolchain. Install ESP-IDF 5.5.1 following Espressif's getting-started guide, then clone the Oído repository from GitHub.
2. Download the model files. The repository README links each model to its Hugging Face page. For a first build, the int8 English model (nemo8.tnm) and its language model (nemo_lm.tlm) give the best accuracy. Place the files in the models/ directory inside the repository.
3. Choose a partition table. The default partition table fits the 14.0 MB int8 model. If you use the int4 model (nemo4.tnm, 8.3 MB), switch to the supplied partitions_nemo4.csv — it leaves a 6 MB app partition free for your own application code.
4. Build and flash. Use the standard ESP-IDF toolchain commands described in the repository README. The project also includes a host build (TASR_MODE=file) that runs the identical C inference code on a PC using audio clips in flash-image format — a reliable way to confirm model behavior before you touch the board.
5. Run the live demo. With the board connected to a PC, use the included Python script to capture microphone input and print transcripts:
python live_demo.py
Switch to the Spanish model:
python live_demo.py --model es
The end-of-speech wait (default 0.8 s) is configurable via CONFIG_TASR_SEG_HANG_MS in the firmware or the --pause flag of live_demo.py, as described in the README.
6. Reproduce the benchmarks. The eval/eval_engine.py script runs the standard accuracy evaluation and eval/make_robust.py generates the noise-robustness numbers. Raw board measurements are saved in results/board_esp32s3.json.
Ideas to Extend It — and Limitations to Know
Ways to go further
- Add wireless output. The int4 model leaves a 6 MB app partition free. That is enough room to add a Wi-Fi or BLE stack that forwards transcripts to a home-automation hub over MQTT without needing a separate microcontroller.
- Build an offline voice assistant. The streaming mode was designed for voice-agent pipelines. Pipe
live_demo.pyoutput to a local language model or a text-to-speech engine running on a companion computer for a fully offline voice assistant with no cloud calls at any stage. - Add a new language. English and Spanish each have dedicated model files. Extending to another language follows the same pipeline: fine-tune the Conformer on a new vocabulary and train a GRU language model, mirroring what was done for Spanish (2,492 hours of training audio from Common Voice, VoxPopuli, Multilingual LibriSpeech, and FLEURS).
- Contribute dual-core support. The second Xtensa LX7 core is the clearest path to real-time operation — the README estimates a perfect 55%-critical-path split would yield roughly 1.1× real time. The dual-core code path is currently disabled because it produces incorrect transcripts on silicon; fixing it is an open problem.
Limitations to plan around
- Not real time yet. At 1.97× real time on one core, a 4-second command produces its transcript about 8.7 seconds after it ends (including the 0.8-second end-of-speech wait). Streaming mode roughly halves that wait but does not reach the 1–2 second target needed for truly interactive voice control.
- No bilingual model. English and Spanish have different vocabularies and separate model files; you cannot switch languages at runtime without reflashing.
- Spanish accuracy caveats. The Spanish benchmark was measured on corpora the model was trained on. Accuracy on phone calls, strong regional accents, or specialized vocabulary will likely be higher than the reported figures.
- PSRAM required. The board must have 8 MB PSRAM. The engine uses up to 2.4 MB as working memory and caches weights in the remainder; boards without PSRAM cannot run Oído.
Oído is a technically rigorous piece of embedded engineering: it delivers accuracy that beats several laptop-class speech recognizers while running on a $5 chip with no network connection required. The main practical caveat is speed — at roughly 2× real time the engine is not yet fast enough for truly interactive voice control on one core — but the streaming mode, the open dual-core problem, and the clean C codebase give contributors concrete targets to work toward.
Sources
github.comlokutor-ai/oido — repository & README lokutor.comOfficial websiteFacts in this article come from the project's public README and GitHub metadata at the time of writing. Images belong to their respective owners and link back to the original source.